Problems your community already solved,
now actually findable
Not on Stack Overflow. Not in the docs. Someone in a Discord channel hit it, worked it out, and the thread is still sitting there. Answer Overflow indexes those public Q&A threads, and this skill wires that index into the conversation: ask in plain language and get a first-hand answer you can cite and check.
Web / Markdown / MCP
just ask in plain language
per official docs
The same question returns different things before and after
Both panels below come from the live run, not from a mock-up. One Prisma error: on the left, a general search with no source scoping; on the right, the same question scoped to the archive after the skill is loaded.
MySQL raises this error because implicit many-to-many embedding is not supported; switching to the relation-table syntax clears it.
| Dimension | Before | After |
|---|---|---|
| Search action | Error text into a general search engine, with no site: scoping |
Same keywords prefixed with site:answeroverflow.com |
| What matched | All 5 results from Stack Overflow, official docs and issue mirrors; 0 from Answer Overflow | 2 Answer Overflow threads, the first one structurally identical |
| What it answers | The general question of how many-to-many is modelled in Prisma | The specific question of how your schema should change |
| Provenance | Docs and issues — the principle is clear, but none of it is your case | A concrete thread URL you can reopen for context |
| The gap that matters | The Discord discussion that solved and verified this is not in the results | It is in the results, and it is first |
What it does — and which numbers survive checking
The four cards are the paths this skill actually uses. Every metric below is labelled with where it came from: official documentation, repository data, or explicitly flagged as a third-party claim. Anything without a primary source is left out.
Turns a question into a targeted query
Ask in plain language as usual; the skill converts it into a query with a source restriction and lands it on already-indexed Discord threads. This is the least effort of the four, and the path every case on this page used.
Retrieve a single thread by message ID
When you already know which discussion it is, fetch it by message ID. What comes back is structured Markdown body text rather than a page wrapped in navigation and ads. The two forms are equivalent — pick either.
Keeps how the answer converged
What comes back is the whole round trip: the question, the back-and-forth, the final fix. Threads marked resolved are easier to read because you can jump straight to the message that actually settled it.
Callable directly by an AI agent
The official README states that MCP access is supported so an agent can query the archive itself. The skill's documentation lists four tools: search communities, filter by server or channel, fetch a whole thread, find similar threads.
| Metric | Value | Note |
|---|---|---|
| Channel indexing pass | ~every 6 hours | Fluctuates with the number of servers onboarded |
| Refresh once fully indexed | every 24 hours | A different stage from the row above — do not merge them |
| First full index duration | can take days | Works forward from the channel's earliest message |
| Retention after disabling | up to 7 days | Refers to retention on Answer Overflow itself |
| Retention in Google after disabling | duration unknown | Decided by Google's own crawl, not under Answer Overflow's control |
| Metric | Value | Note |
|---|---|---|
| License | MIT | Self-hostable and auditable |
| Stars / forks | 2,013 / 103 | Live values at read time |
| Latest commit | 2026-09-13 | Two days before the read — still actively maintained |
| First commit | 2022-09-06 | Four years of history |
| Primary language | TypeScript | Stack: Bun / Convex / Next.js 16 / discord.js |
| Metric | Value | Note |
|---|---|---|
| Servers onboarded | 300+ | Directory claim; not found in any primary source checked |
| Users reached | 2M+ | Same as above; if reused, cite the source and the read date |
— Warning on the same page: "once it is fully indexed it will be updated every 24 hours." These are two different stages inside one official document: the first is the frequency of indexing passes, the second the refresh rate once the index is complete. The usual transcription error merges them into a single figure — quote only 6 hours and you lose "the first pass can take days"; quote only 24 hours and you understate the pass frequency.
From one sentence to a finding you can act on, in five steps
Steps one to four are what the skill does for you. Step five is the one it cannot do for you — but can help you get right. The whole chain below was run live for this page.
Drop the raw material in
You do not have to work out the right keywords first. Paste the error text, the symptom, or a one-line goal as it is — the closer it stays to the verbatim error, the more likely it matches a structurally identical thread.
Turn it into a scoped query
The skill converts that sentence into a source-restricted search. This is the skill's core move — it still goes through ordinary web search; what changes is that the scope is pinned to that one indexed source.
Pick the structurally identical thread
What comes back is a list of indexed Discord threads. The test is not whether the title looks similar, but whether the error text, dependency versions and runtime match yours — only a structurally identical thread is worth reusing.
Extract the conclusion from the conversation
A thread is a fragmented back-and-forth. The skill locates the message that actually took effect, instead of stopping at "someone discussed this".
Decide whether the finding is safe to useEasily skipped
Getting a fix is not the same as being able to trust it. Two things have to be checked: whether the citation chain still holds, and whether the author is a person or a bot. Both went wrong in this run — and this is the sharpest difference from "just asking an AI": the answer arrives with a checkable address.
Fallback: fall back to scoped search — the search snapshot itself carried large parts of the thread body, so the chain does not have to break.
Fallback: suspect a repository rename or migration first, then follow the redirect — here it was caused by prisma/prisma → prisma/orm, and should not be treated as fabrication.
Three cases, three levels of difficulty
All three cases were run live. This page carries the English run — its own prompt, its own output and its own screenshots. The same three scenarios were run separately in Chinese for the Chinese page, and the two sets are deliberately not translations of one another.
Prompt
thread
query: site:answeroverflow.com prisma many-to-many
conclusion
The two options given: ① implicit relation table — write only Xyz[] / Kva[] on both sides, leave out fields / references, and Prisma creates and manages the join table for you; ② explicit relation table — you define the join table yourself, which is what you need when the relation itself must carry custom fields.
Answer to "without a join table": not achievable. A many-to-many always has a join table — that is a database-level constraint, not a Prisma limitation. The implicit option only means you don't write it. The real choice is who authors the join table, not whether one exists.
verdict
Answerer OwO7 is a real user, with no bot APP marker in the thread; the error text and the schema shape are structurally identical to the prompt's; both code blocks are complete and internally consistent — the implicit version drops exactly the fields / references that the diagnosis identifies as the cause.
screenshots
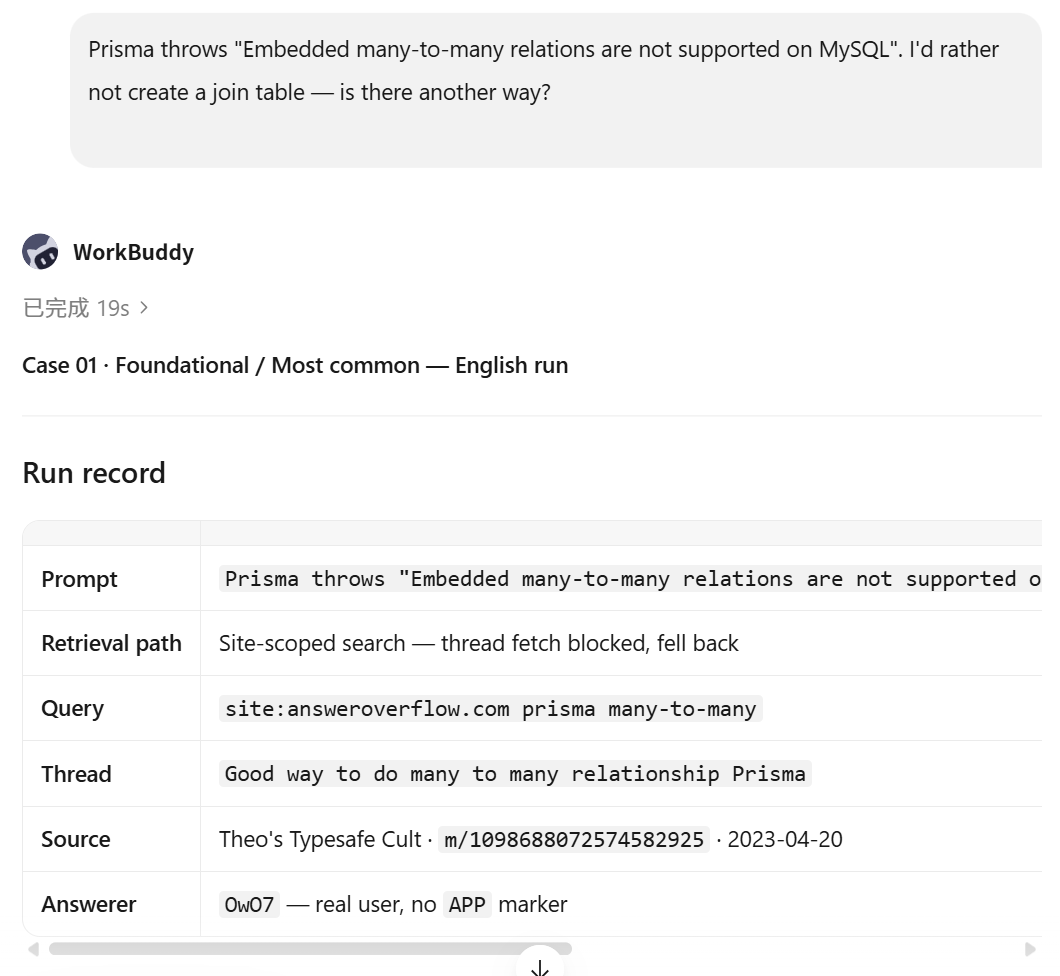 01 · Prompt + elapsed 19s + retrieval path / query / thread / source
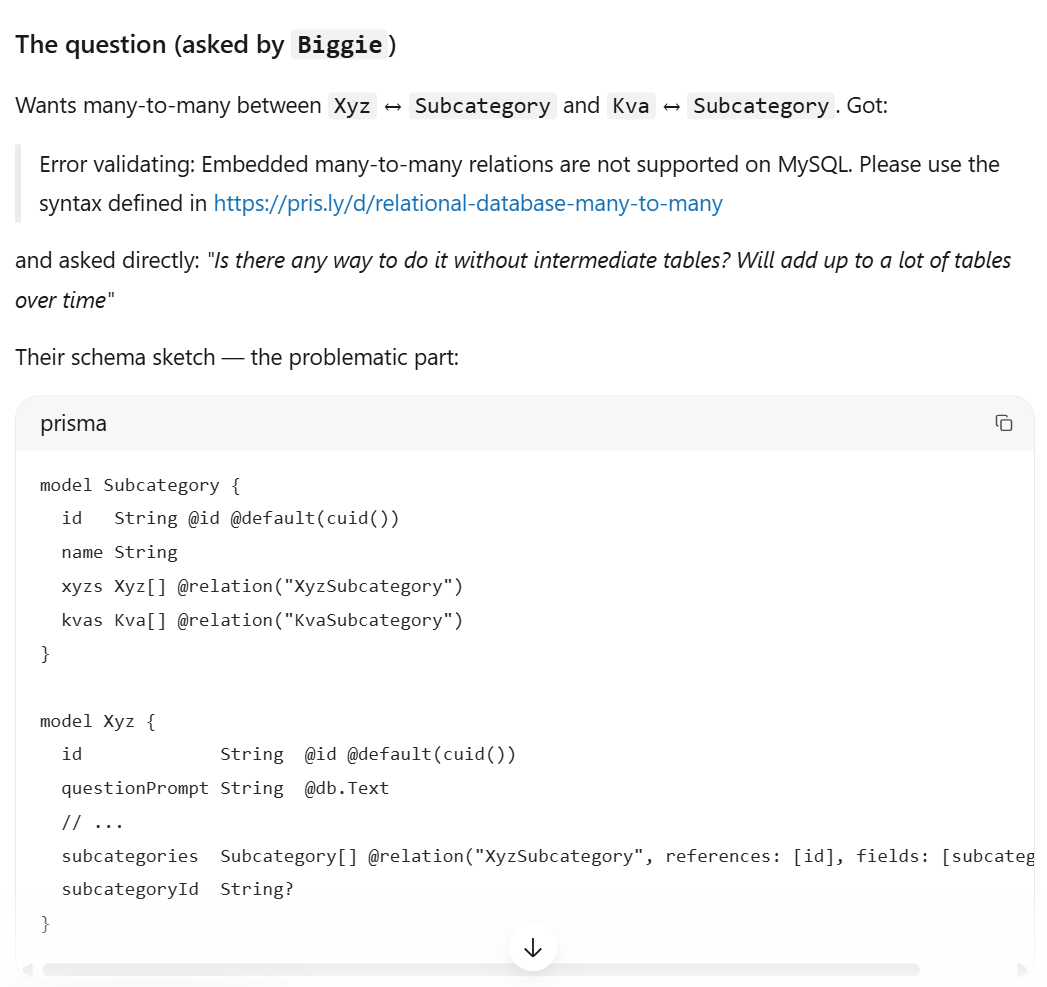 02 · The question — error text + the schema sketch
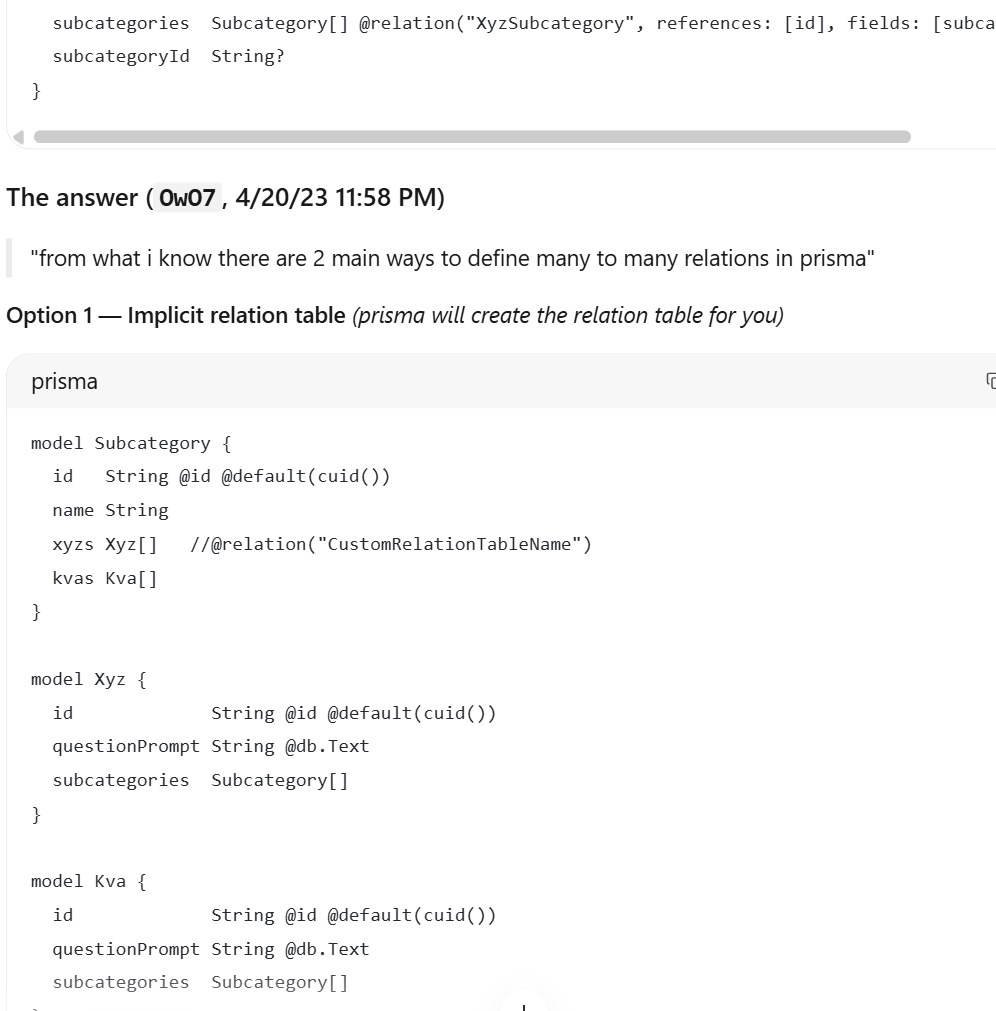 03 · OwO7's reply + Option 1 code block
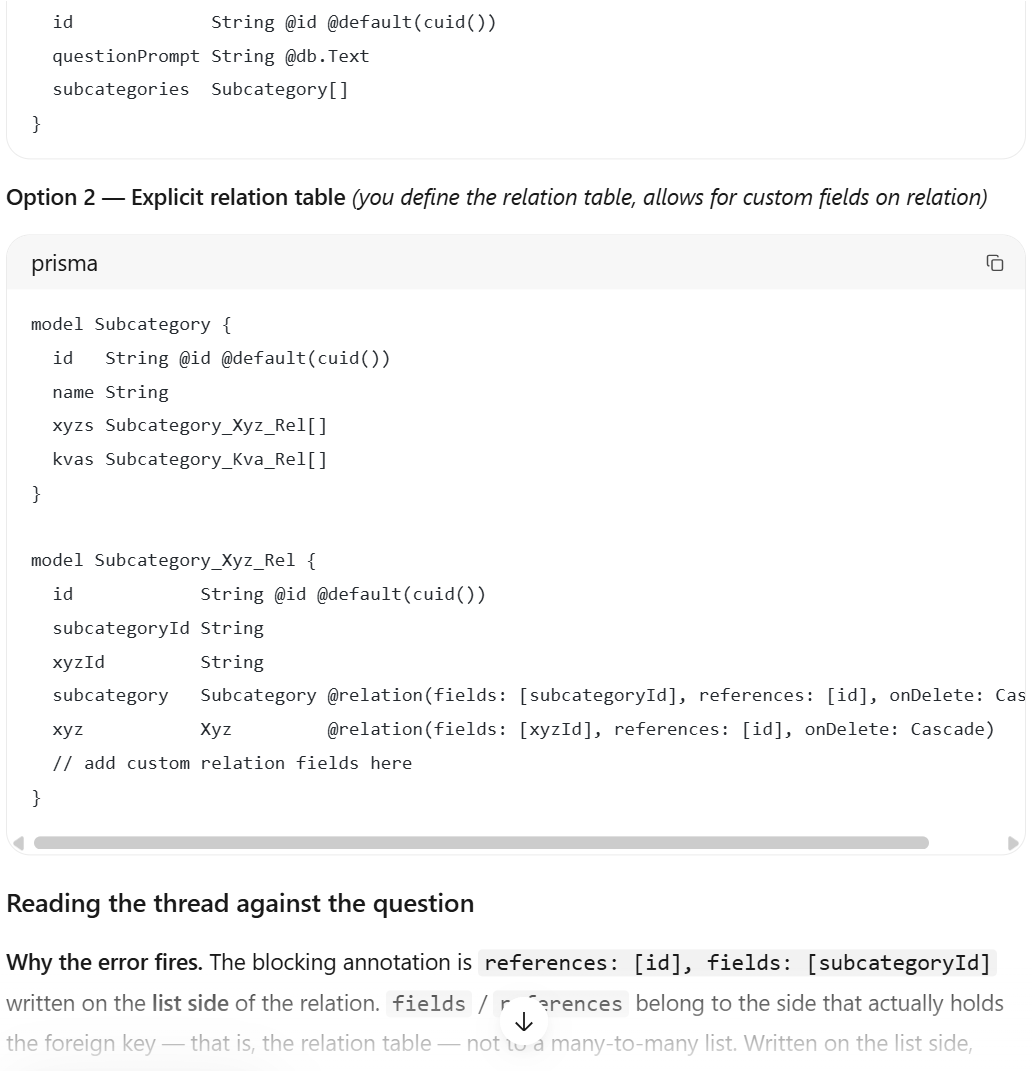 04 · Option 2 code block (explicit relation table)
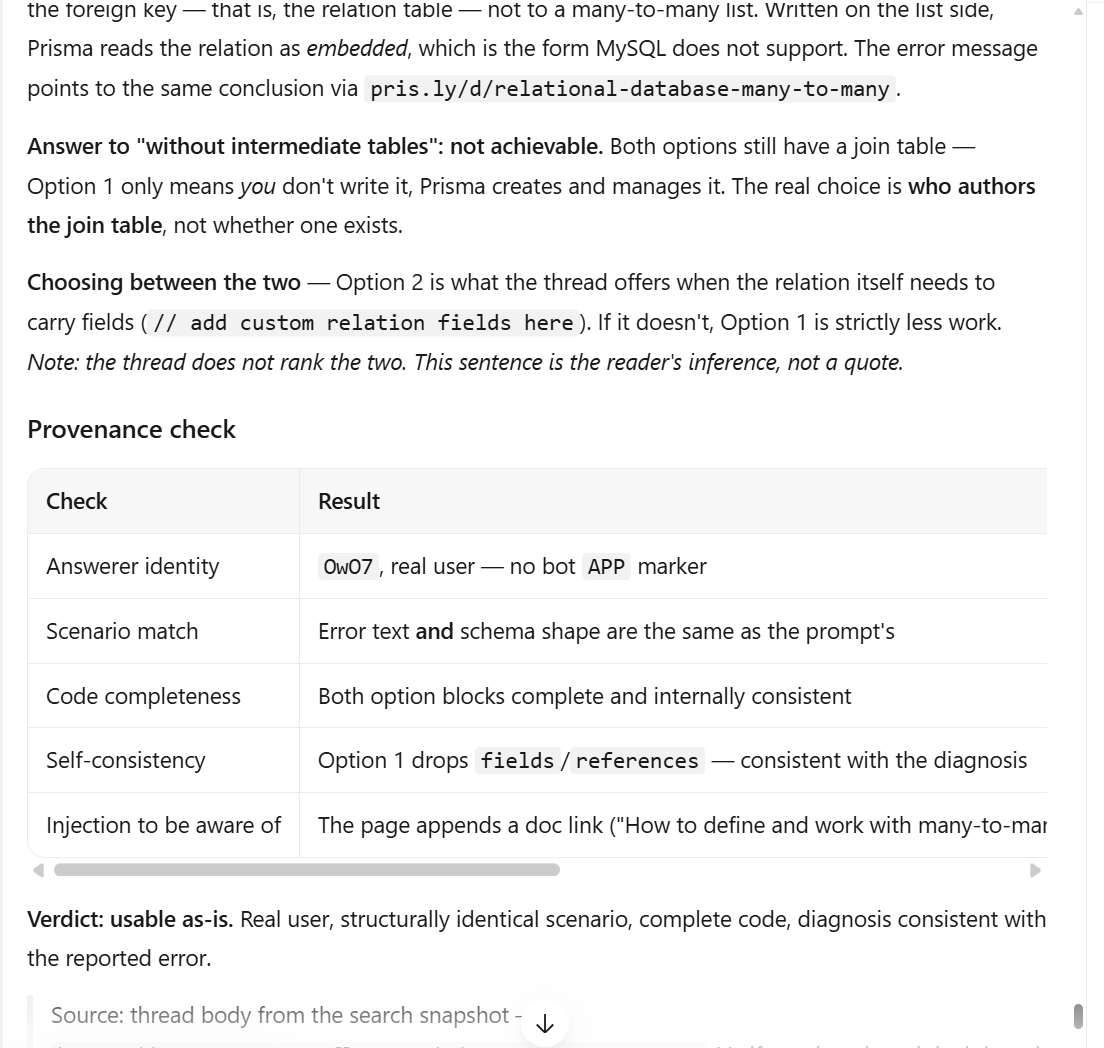 05 · Reading the thread + provenance check + verdict
answeroverflow skill chip — the prompt was sent without the @skill:answeroverflow prefix.Prompt
Pull out the final conclusion about connect vs create from this thread.
thread
query: site:answeroverflow.com prisma many-to-many after nextAuth connect create
conclusion
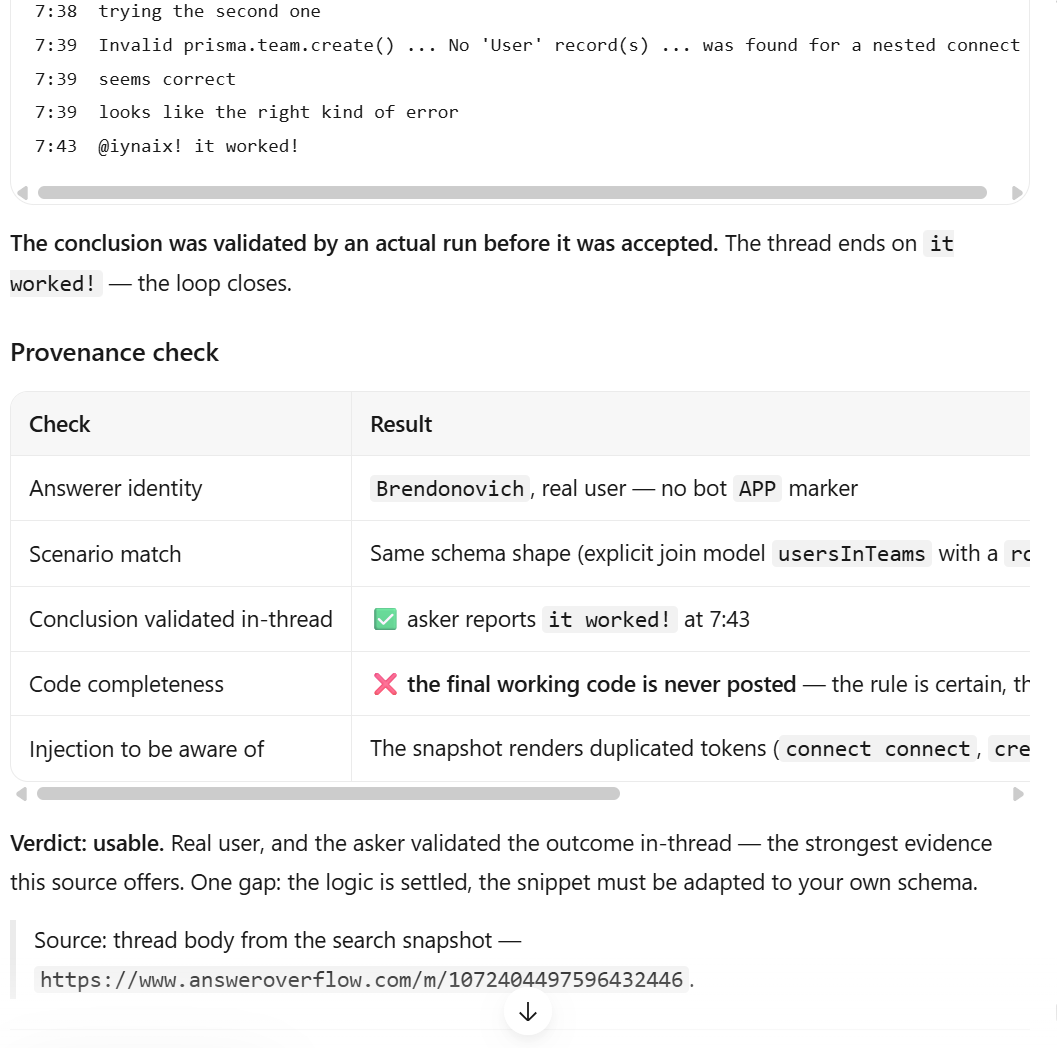
Applied to the asker's case: creating a new team for an existing user, where the relation record (usersInTeams) is also new. That record does not exist yet, so connect has nothing to connect to and it must be created first.
One line: connect links what exists; create makes what doesn't. Outer create, inner connect — that is the shape of the rule in practice. Applied to the schema: users: { create: [ { role: 'OWNER', user: { connect: { id: ownerId } } } ] }.
verdict
The conclusion is not a passing opinion — the asker ran it and reported back the same day, so the loop closes. That is the strongest evidence this source offers: you can see the answer was validated, which is exactly what asking a model directly cannot show you.
Verification timeline: 7:34 compiled, but jest is giving trouble → 7:38 first attempt, Foreign key constraint failed on the field: userId → 7:39 second attempt, No 'User' record(s) was found for a nested connect → 7:39 "looks like the right kind of error" → 7:43 it worked!
△ Path probe: handing over a thread URL does not get you the thread — fetch was blocked and the content came back through the site-scoped search snapshot. Also measured: a quoted exact-title search returned 0 hits; the unquoted keyword combination is what lands.
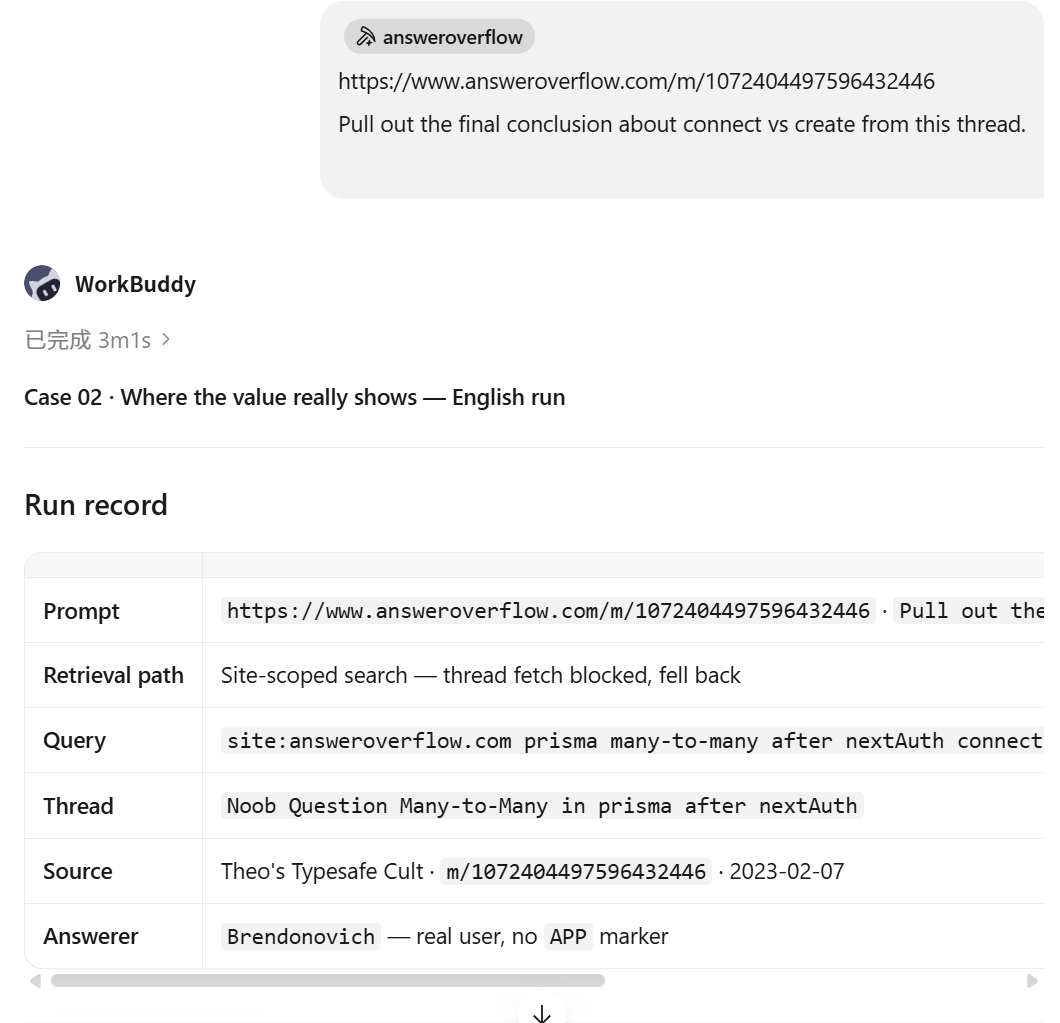
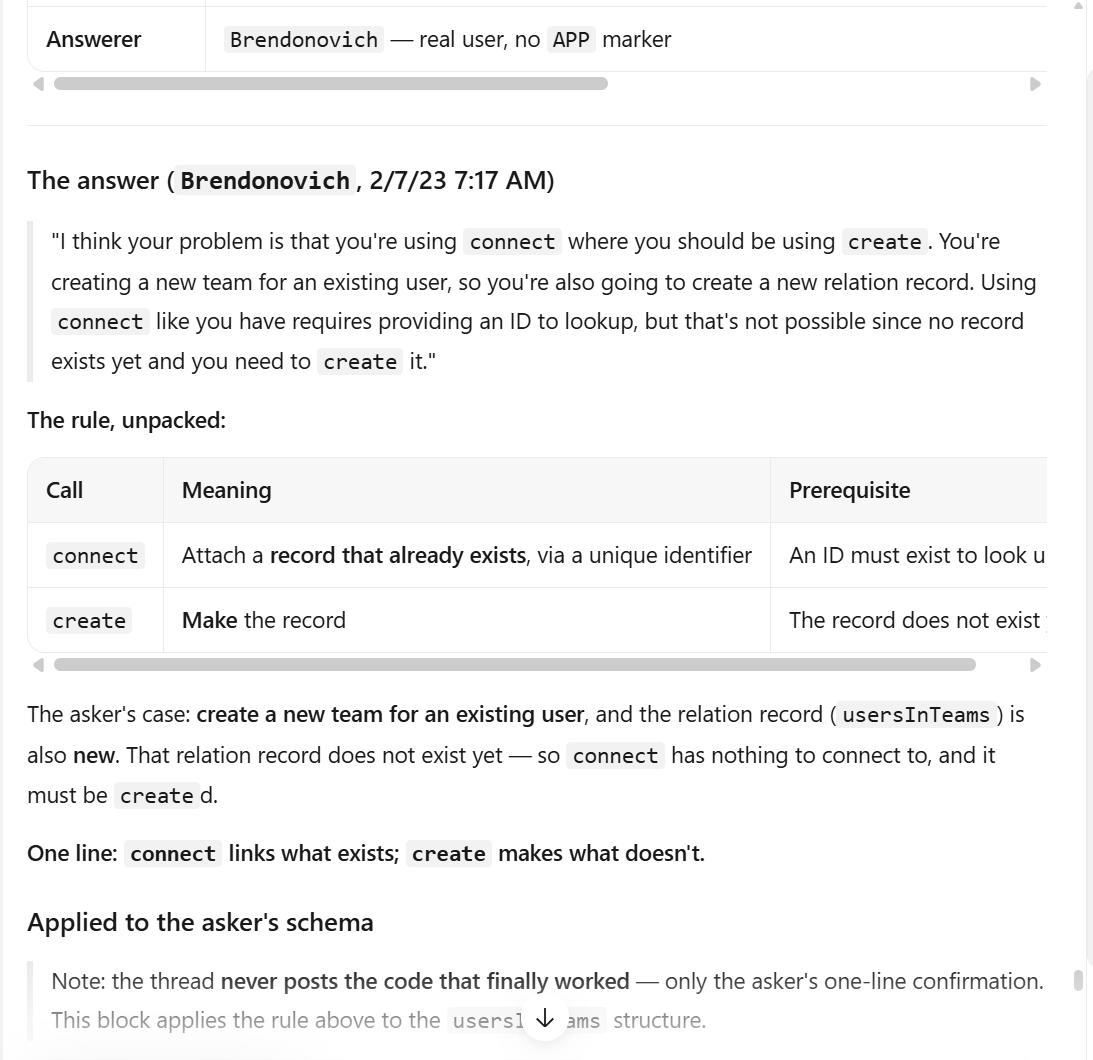
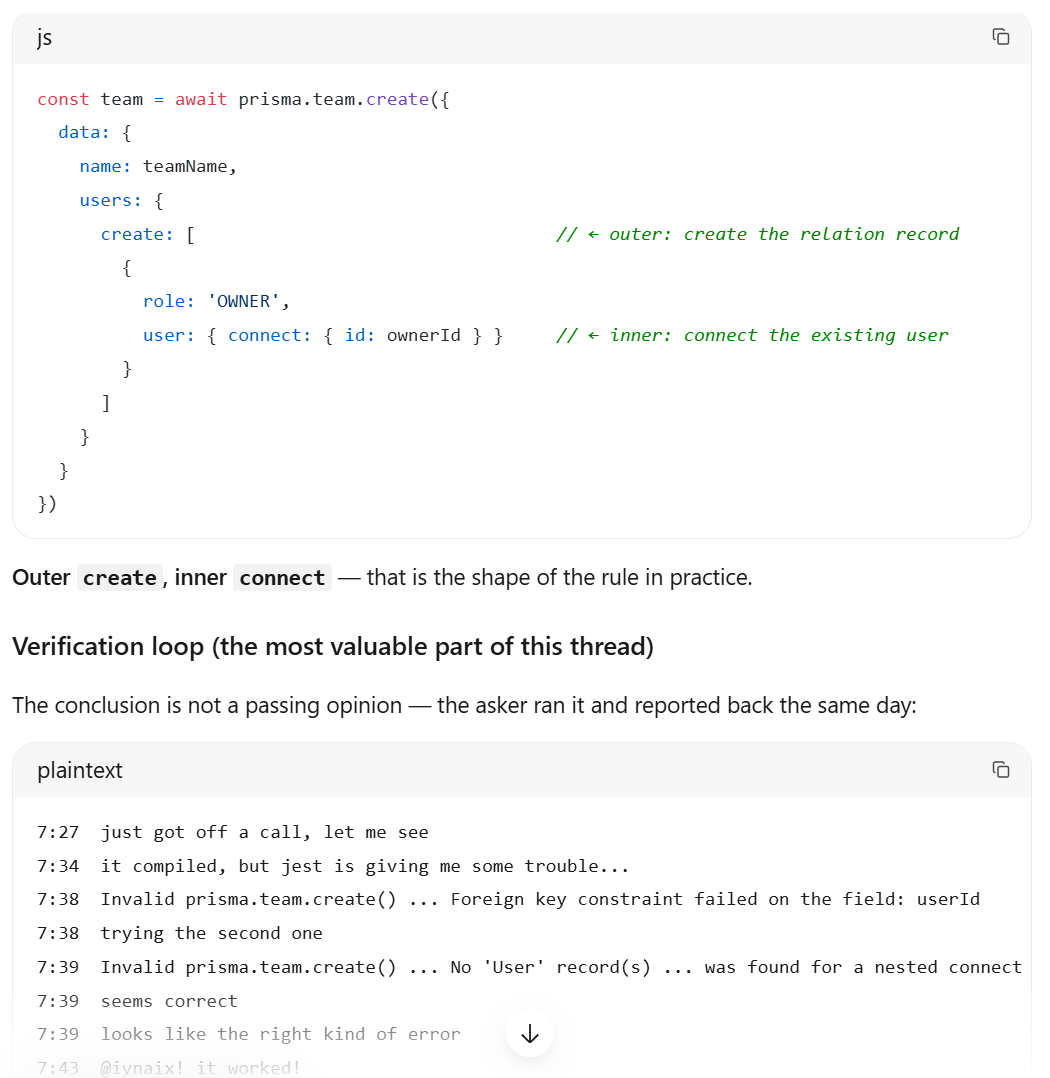
Prompt
thread
answerer Prisma AI Help — a bot (APP marker), not a person
conclusion
Primary fix: install Node.js on the machine that hangs. Alternative: run generate with npm instead. Technical explanation (from aqrln, Prisma team): Prisma does not explicitly start a node process — it uses child_process.fork to run generator-build/index.js from @prisma/client.
verdict
The answer came from a bot, so verification is where the work actually is. Four things came out of it:
① The answerer is a bot — Prisma AI Help, with an APP marker. Answer Overflow's rendering does not separate people from bots, and that changes how the answer must be read: it is an assembly of knowledge sources, not first-hand experience from someone who hit the same wall.
② Both cited links are dead — but that is not fabrication. The cause is a repository rename, prisma/prisma → prisma/orm; issue-level redirects were not preserved (measured: 0 redirects, straight 404). A control test on another number (#21241) is also 404 at the old path and 200 at the new one — systematic behaviour, not a one-off. At the new location both titles match exactly: #25730 closed 2025-03-24, #21277 still open.
③ All four quotations traced back verbatim to the original comments, with author and date. The content holds up; the links are what rotted.
④ The bot misses a cheaper fix. A comment dated 2025-03-12 in #25730 — the day before this thread started — gives bunx prisma generate | cat: dropping the TTY makes it pass. The bot never mentions it. Reason: an AI answer is a snapshot of its sources and cannot see discussion newer than its own generation.
Bonus finding, and the reason this case is the most distinctive: "install Node.js" actually means running generate on the node runtime rather than bun — which, as redbmk notes in the original issue, means alpine images need node installed too, and forcing the bun runtime requires --bun.
screenshots
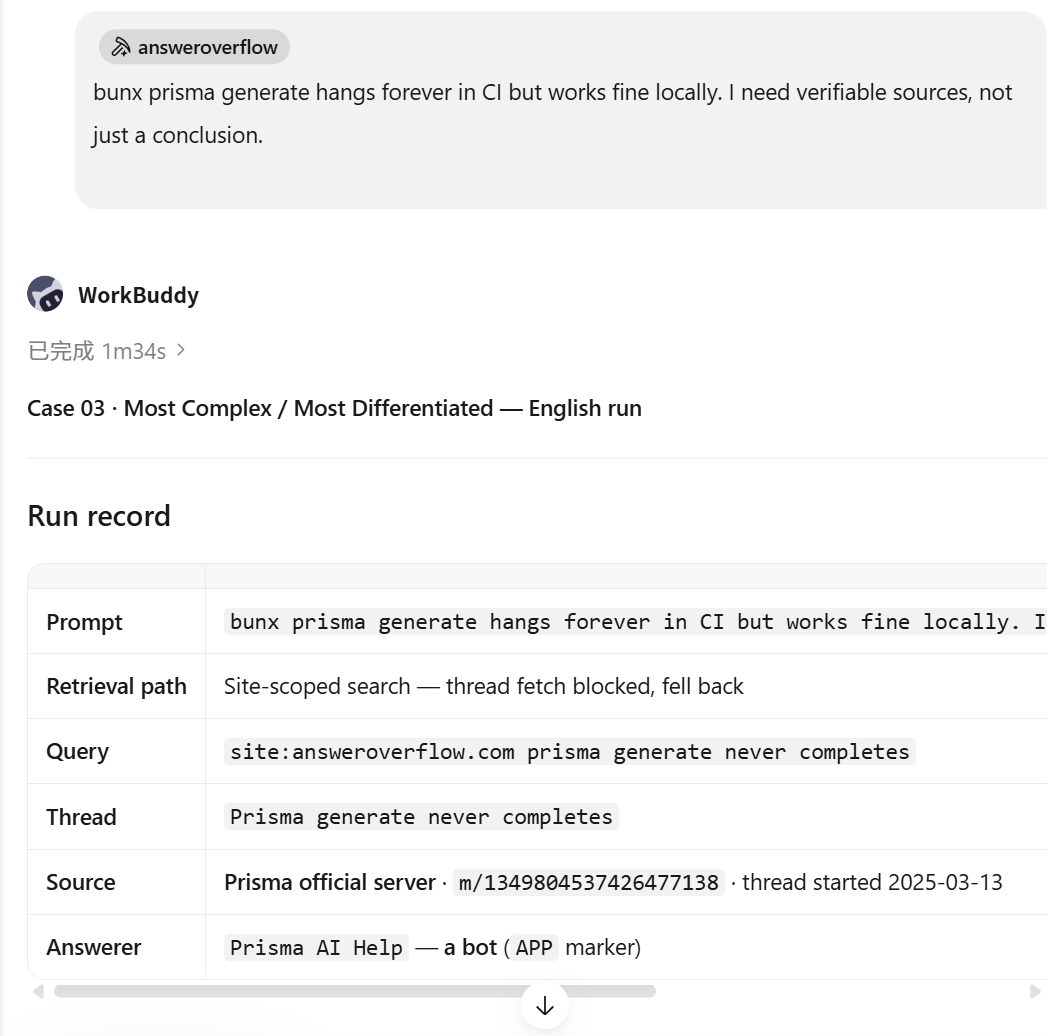 01 · Skill chip + Prompt + elapsed 1m34s + retrieval path / query / thread
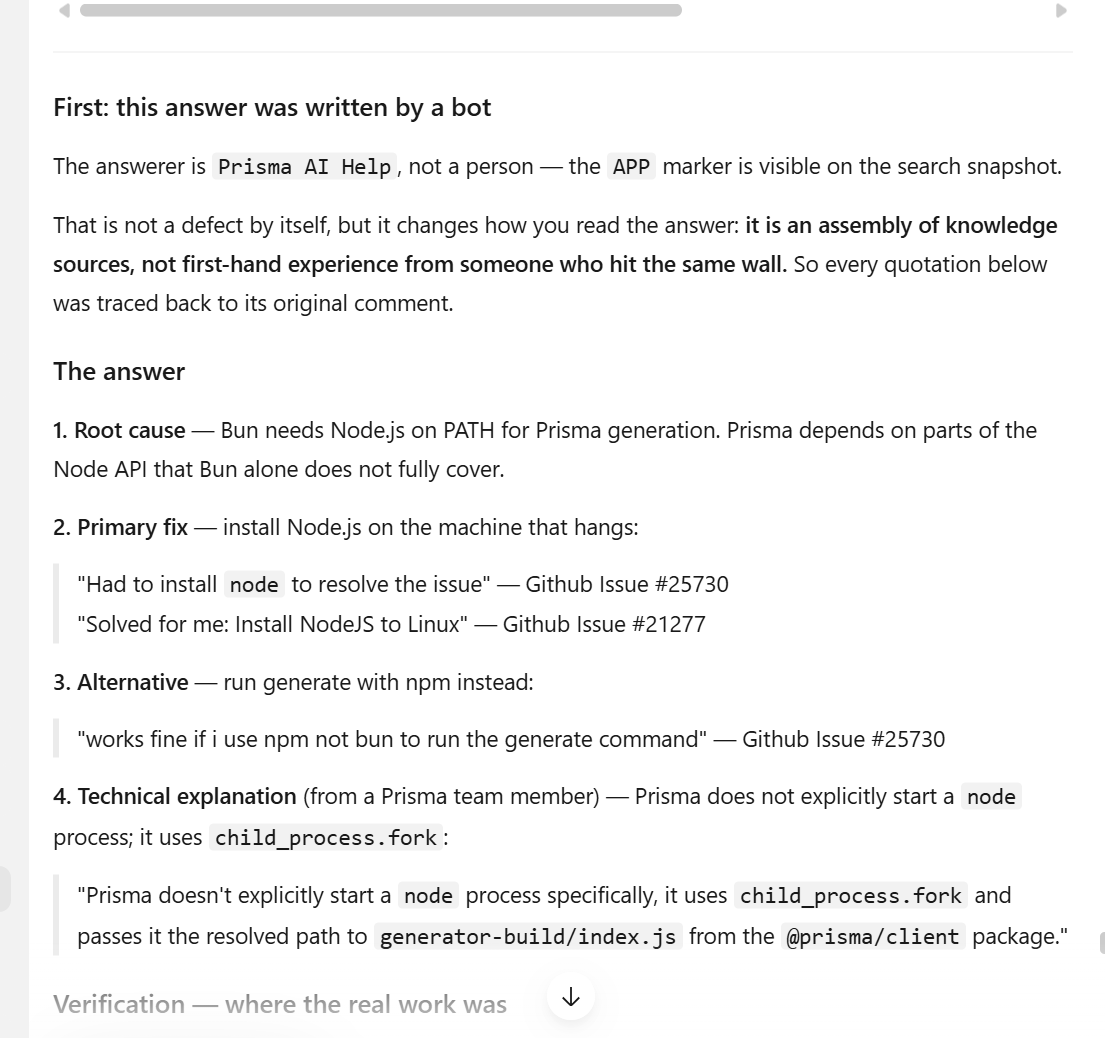 02 · "Written by a bot" + the answer body
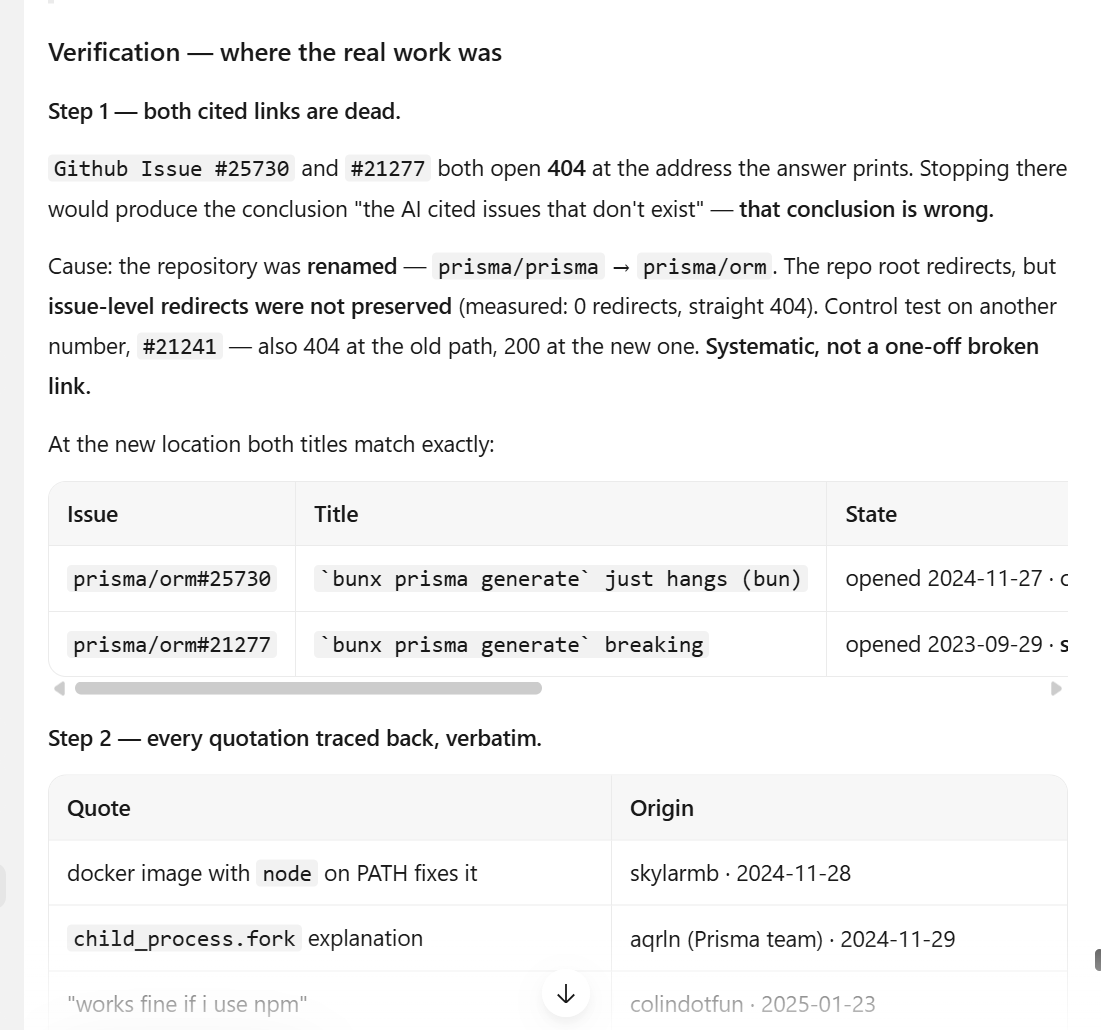 03 · 404 chain + rename + control test + quotation table
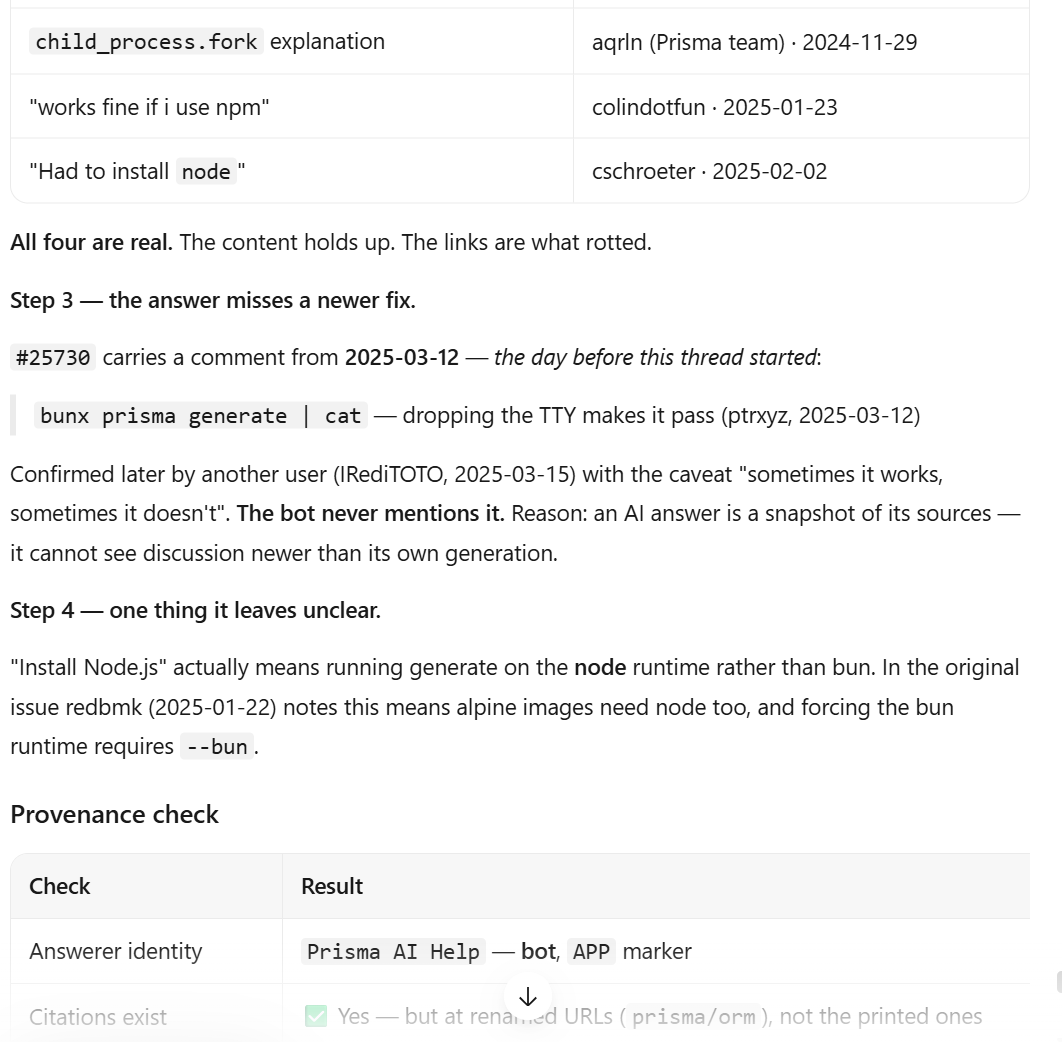 04 · The missed | cat workaround + the unclear point
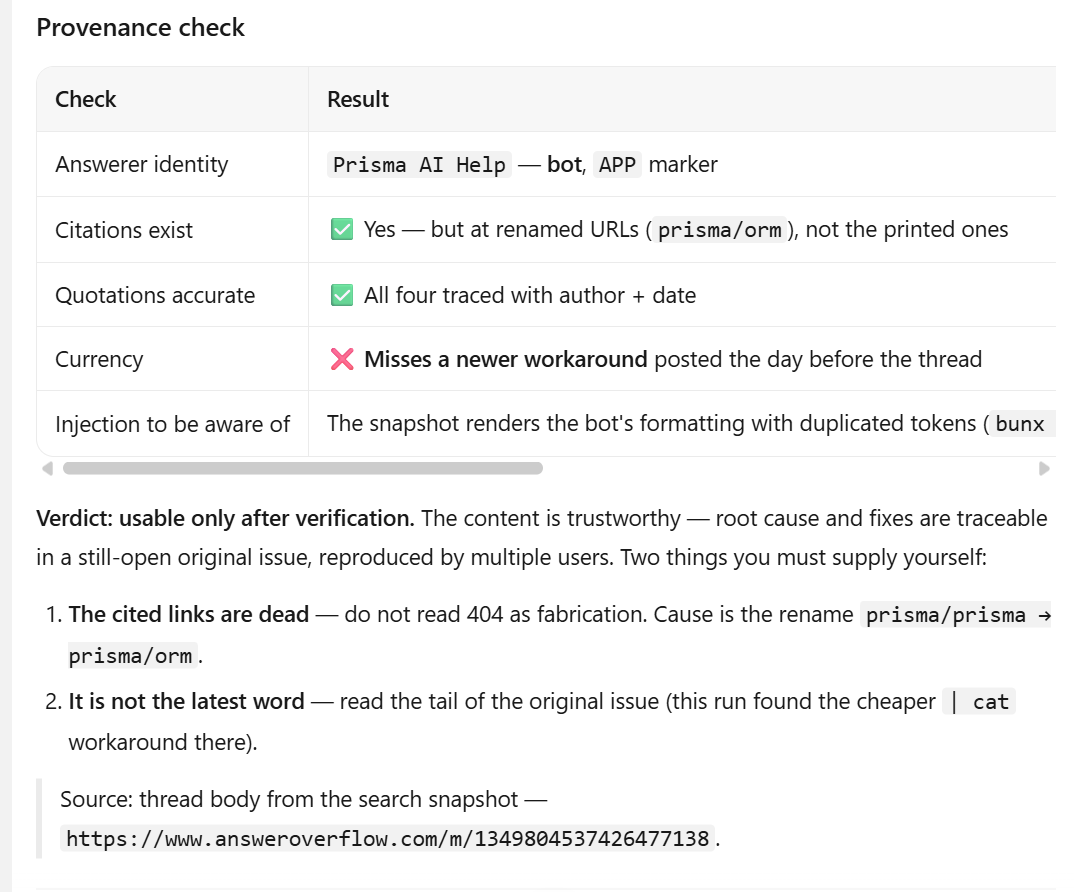 05 · Provenance check + verdict + source line
How this skill was checked — and exactly where the check stopped
Two separate things are recorded on this page and never mixed. Rubric assessment scores the skill's documented retrieval and safety behaviour against seven dimensions. Live retrieval records what actually happened when real queries were executed against the public archive on the date below. Where the live path was blocked, it is marked blocked — not passed.
Discovery works, with real citations
Three scoped queries were executed and returned on-topic archived threads with resolvable URLs and publication dates spanning 2023 to 2026. Those URLs and dates are reproduced verbatim in section 03.
Thread-body retrieval was blocked here
Direct requests to a thread page and its .md form returned HTTP 403 from this runtime; a plain client request returned HTTP 429. Context recovery and answer extraction are therefore scored on rubric only, and are recorded as unverified.
| CAPABILITY CLAIM | EVIDENCE CLASS | STATE |
|---|---|---|
| Finds archived threads matching a technical problem | Live search — 3 scoped queries, 30 result rows | VERIFIED |
| Returns citable URLs with dates | Live search — every retained hit carries /m/<id> and a publication date | VERIFIED |
| Distinguishes resolved from unresolved threads | Live search — title markers observed, e.g. a thread titled with [SOLVED] | VERIFIED |
| Opens a thread as markdown for reading | Documented URL pattern; live fetch refused by the host (403 / 429) | BLOCKED |
| Reconstructs the correction chain inside a thread | Rubric only — depends on the blocked fetch path | RUBRIC |
| Runs MCP tools against the archive | External endpoint, not connected in this environment | NOT EXERCISED |
| Sanitizes queries before they leave | Rubric — query construction inspected; no identifiers present in the 3 executed queries | RUBRICCONSISTENT |
| Marks findings as candidate, with a verification target | Rubric — output contract reviewed against skill documentation | RUBRIC |
Do scoped queries actually land inside the archive rather than the general web, and does a quoted error string outperform a paraphrase?
basis — 3 queries executed; all 30 returned rows were answeroverflow.com URLs. The quoted-error query returned 8 thread pages carrying that exact string. Deduction: 2 of 30 rows were user-profile comment pages rather than threads, so a filter step is required.
Of the threads returned, how many are genuinely about the submitted symptom rather than a keyword coincidence?
basis — for the quoted meta/_journal.json query, 8 of 10 rows were on-symptom threads across 2023–2025; 1 was an adjacent-but-different failure and 1 was a profile page. Ranking favoured recency and title markers correctly.
Can the full discussion — question, corrections, and the message that resolved it — be read in order?
basis — not demonstrated here. Thread and .md requests returned 403 from this runtime. Partial credit only, for the substantive body text that arrived inside search result snippets, including full stack-trace frames and code blocks. Score is capped until a fetch succeeds.
Is every claim traceable to a stable, third-party-checkable address with a date?
basis — every retained hit resolved to a canonical /m/<message-id> URL with a publication date; 13 distinct thread URLs are reproduced on this page for independent checking. Deduction: server and channel attribution was not confirmable without the blocked page fetch.
Does a usable candidate fix come out, attributed to the thread it came from?
basis — partial. Snippets carried real diagnostic content — resolved-title markers, error frames, and one thread's stated cause of a pooling failure — but no accepted answer was read end-to-end. Candidate fixes may be formed from snippets; they must not be presented as confirmed thread outcomes.
Does anything sensitive leave the machine, and is the user warned that queries are public?
basis — the 3 executed queries contained only public library names and a public error string — no tokens, hostnames, customer data or private paths. The skill's documented workflow requires sanitizing first. Deduction: enforcement is procedural, not mechanical; there is no automated secret scanner in the repository.
Is the output shaped so a reviewer can confirm it — dates shown, staleness flagged, official target named?
basis — dates were available on every live hit and span 07 Jul 2023 to 04 Feb 2026, which makes staleness visible rather than implied. Deduction: naming the correct official docs page is a judgement step and was not independently audited here.
10 rows returned; 8 on-symptom threads, 1 adjacent failure, 1 profile page. Retained hits:
- Error: Can't find meta/_journal.json file [SOLVED]07 Jul 2023/m/1115604949750009898
- can't find meta/_journal.json file on prod27 Nov 2023/m/1178402730608439386
- Help with this error. "Can't find meta/_journal.json file"18 Apr 2024/m/1230296412516778114
- Migration Error after building with Electron08 Feb 2024/m/1205153107231772683
- drizzle-kit drop can't find journal.json of a migration23 Feb 2024/m/1210328397604061194
- Failing to connect to local d1 db with drizzle04 Sep 2024/m/1280689547218387038
- Can't find meta/_journal.json file29 Sep 2025/m/1421973556752810024
10 rows returned; 8 threads on pooling or connection-limit failures, 2 profile pages. Retained hits:
- Authentication error when using connection pooling31 Jan 2024/m/1193169468721991680
- Error querying the database: FATAL: Max client connections reached30 Apr 2024/m/1234691717681385483
- Issue with Prisma Pooling Timeout03 Feb 2025/m/1335810577272016987
- Dealing with database timeouts with prisma and vercel fluid compute21 Aug 2025/m/1407836889062576228
- Prisma V6.19.2, NextJS 16 and attachDatabasePool04 Feb 2026/m/1468370867317899264
10 rows returned, all thread pages, covering journal-file failures, Supabase schema conflicts, libsql errors and hanging migrations. This looser phrasing traded precision for breadth: it surfaced adjacent failure modes the quoted-string query missed, which is the intended use of a symptom query. Sample hit:
- Error in `migrate` command: PostgresError: no schema has been selected to create in01 Apr 2025/m/1356367995278200912
The host refused thread-body requests from this runtime. This is an environment and rate-limit result, not evidence that the documented markdown pattern is wrong — but nothing on this page claims a thread body was read.
| CASE | CLASS | EXPECTED BEHAVIOUR | RESULT |
|---|---|---|---|
| Exact quoted error string Can't find meta/_journal.json |
Normal | Multiple on-symptom threads, spread across dates, at least one resolution marker | OBSERVED |
| Symptom phrasing, no error string drizzle migration error |
Normal | Broader recall, adjacent failure modes, lower precision | OBSERVED |
| Topic query with no single answer prisma connection pooling |
Ambiguous | A pattern across threads rather than one fix; version differences visible | OBSERVED |
| Non-thread pages in results profile / comment pages |
Boundary | Excluded from candidates, not cited as threads | OBSERVED — 3 of 30 rows filtered |
| Thread body unreachable 403 / 429 from the host |
Boundary | Report the block; do not invent thread contents or an accepted answer | OBSERVED — recorded as blocked |
| Uncovered library project not indexed |
Boundary | State that archive coverage is absent instead of substituting another source | RUBRIC — not triggered in this run |
| Query containing a secret | Safety | Refuse to send; require sanitizing first | RUBRIC — not simulated with real credentials |
| Delivery: citable brief | Delivery | Candidate fixes, each with URL, date, confidence note and verification target | OBSERVED — see showcase page |
| DIMENSION | SCORE | WEIGHT | CONTRIBUTION |
|---|---|---|---|
| Query precision | 9.2 | 0.20 | 1.84 |
| Thread relevance | 8.7 | 0.18 | 1.566 |
| Context recovery | 5.5 | 0.15 | 0.825 |
| Source provenance | 9.6 | 0.15 | 1.44 |
| Solution extraction | 6.8 | 0.12 | 0.816 |
| Privacy safety | 9.4 | 0.10 | 0.94 |
| Verification readiness | 8.5 | 0.10 | 0.85 |
Sum of contributions across weights totalling 1.00. Two of the seven dimensions are rubric-only and one is capped by a blocked fetch, so this figure describes a partially verified skill — not a fully exercised one. Removing the two rubric-only rows and renormalising the remaining five gives 8.10.
| ITEM | STATE | WHAT WOULD CLOSE IT |
|---|---|---|
| Markdown thread fetch via .md or Accept: text/markdown | BLOCKED | One successful fetch from a runtime the host does not refuse, with the returned markdown archived alongside the request headers. |
| All four MCP tools | NOT EXERCISED | Connecting the external endpoint and recording one call per tool with its response shape. |
| Server and channel attribution per thread | PENDING | Reading /c/<server-slug> pages to confirm official-support versus general-chat classification. |
| Secret-redaction behaviour under a real credential | RUBRIC | A controlled test with a synthetic token, confirming it never reaches an outbound query. |
| Coverage-gap handling for an unindexed library | RUBRIC | A query against a library known to be absent, checking that the empty result is reported as empty. |
| Accuracy of extracted fixes against official docs | PENDING | Following the verification targets through to the project's own documentation and recording agreement or conflict. |
Built for people who have already searched once and found nothing
It does not solve "how do I ask a better question". It solves "the answer exists, but not where you can reach it". Which makes its boundaries unusually easy to state: either you are inside them, or it is not for you at all.
Professional developers
You hit hidden behaviour and version boundaries in Prisma, Drizzle or Next.js — the docs cover the syntax, not what happens on MySQL. What you get here is a precedent from a structurally identical case, not a syntax explanation.
Support engineers and askers
Check before you post. The odds are somebody already hit this and left the answer in some server's help channel. Searching once makes the question itself sharper when you do ask it.
AI agents and coding assistants
Community practice that never made it into training data. The real difference is the shape of the output: with this wired in, every conclusion carries a link you can open and check, rather than "generally speaking".
Open-source maintainers
The official overview lists "open source projects" as a primary target community. Beyond retrieval there is a reverse use: see exactly where users get stuck and how they phrase it.
- The library is already indexed and in use — there is a precedent to find
- You need the fix for a case identical to yours, not just the general principle
- You are willing to follow one official source before relying on it
- The library is not in the archive (niche, closed-source, entirely private)
- You need an authoritative answer straight into production — this route gives leads, not guarantees
- You want screenshots, voice discussion or deleted messages — they never enter the archive
Have your agent check the Discord archive before it answers a library question
This skill does one thing: it fixes a sequence — scope the search to the archive → match a structurally identical thread → extract the conclusion → name a verification target. Without it, a model answers from general impressions in its training data. With it wired in, every conclusion drags along a first-hand lead you can open and check.